Many people, when they first hear about Rollups, encounter a counterintuitive statement: a Rollup can “compress 10,000 transactions into one.”
This sounds like file compression—as if you stuffed a large zip file into a small envelope and sent it to Ethereum. But if that were really the case, a problem would arise: if a Rollup simply made the data smaller, why would Ethereum believe that these transactions actually happened and that the result is correct? A compressed file by itself does not make transactions trustworthy.
To understand Rollups, the key is not to think about “how the data gets smaller,” but to think about “what work Ethereum was originally doing, and where the Rollup moved that work.” This article will follow that question step by step: why Ethereum cannot process more transactions, what a Rollup actually does, where its security comes from, and why it still is not unlimited scaling.
Why do we need to “compress 10,000 transactions into one”
First, let’s look at what Ethereum itself is doing.
Ethereum is a Layer 1 blockchain, often called L1. On L1, every transaction needs to be verified and executed by a large number of nodes in the network, and the network-wide account state must be updated. “Execution” here does not mean simply recording something; it means actually running the transaction logic: how many coins were transferred, which contract was called, how balances change—all of it has to be computed.
This design is the source of Ethereum’s security, but it is also its bottleneck. The more transactions there are, the more work the entire network has to repeat. Every transaction must be executed once by thousands of nodes, so the cost rises linearly with the number of transactions. When the network is congested, users can only keep raising fees to get processed first, making transactions both slow and expensive.
So a natural idea emerged: can we avoid putting every single transaction on L1 and executing it one by one?
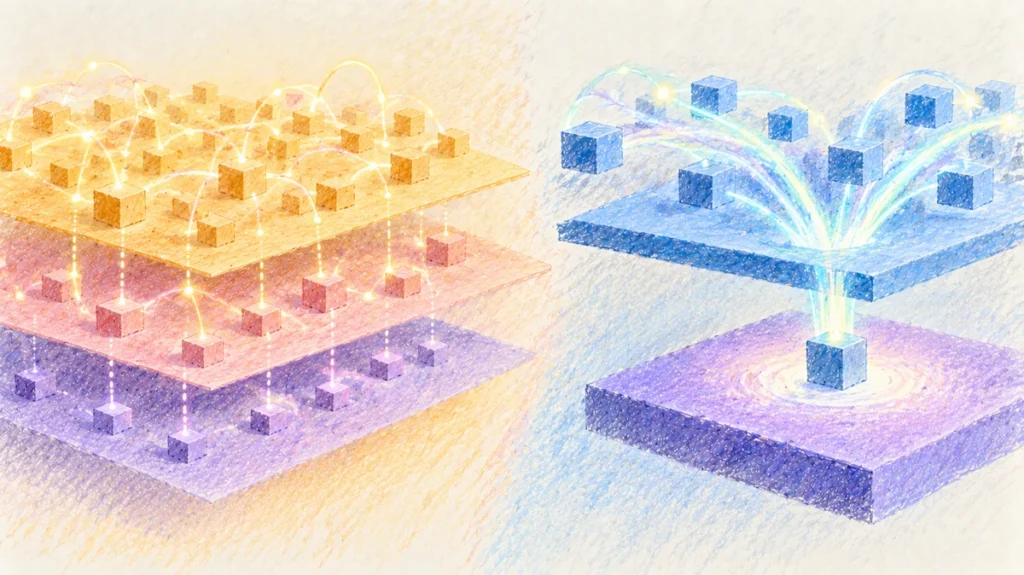
Suppose there are 10,000 transactions. If they are all executed one by one on L1, then L1 has to execute 10,000 times. But if we take another approach—execute these 10,000 transactions somewhere else, and then publish only “the data of this batch of transactions” and “the result after execution” to L1—then L1 no longer needs to repeat those 10,000 executions; it only needs to receive this batch of data and record this result.
This is the real meaning of “10,000 compressed into one.” It is not deleting information or compressing it losslessly; rather, it packages the verification burden of 10,000 transactions into a single batch, turning L1 from “a worker executing one by one” into “a settlement party checking results.”
It should be emphasized that the reason costs drop here is not how much smaller the data file becomes, but that what L1 needs to do has changed. It no longer needs to execute 10,000 computations; instead, it mainly bears the cost of publishing this batch of data. This also explains why this approach can maintain both lower costs and high security—the work of execution has been moved away, but settlement remains on Ethereum.
The core of a Rollup is not compression, but offloading execution
Once you understand the idea above, the basic structure of a Rollup becomes clear.
A Rollup is a chain that runs outside Ethereum and is a type of Layer 2 (L2). Users normally initiate transactions on this Rollup chain, rather than operating directly on the mainnet. These transactions are received by an actor responsible for ordering and execution—usually called a sequencer or operator. It orders transactions, executes them, and then packs the transactions from a period of time into a batch.
At this point, many people mistakenly think: since execution all happens off-chain, doesn’t Ethereum know nothing? That is not the case.
The key is that although execution happens off-chain, the results and transaction data still have to be published to L1. Specifically, a Rollup submits two things to the Rollup contract on Ethereum:
- the data of this batch of transactions itself, or information sufficient to recover that data;
- the state commitment after execution, usually represented as a new state root.
The state root can be understood as “a short summary of all current account states.” It is like a fingerprint of a book’s table of contents: you do not need to copy the whole book; as long as you remember this fingerprint, it can represent the state at a certain moment. Once this batch of transactions changes account balances, the state root changes accordingly.
So how does L1 “believe” this result? The answer is: the L1 contract does not need to re-execute every transaction; it only needs to verify whether the commitment of this batch is valid. In different Rollup schemes, how “valid” is determined differs, and we will discuss that in detail later. But the core logic is the same: L1 changes from executor to settler and verifier.
A common analogy is expense reimbursement: employees process their own expense reports while keeping original receipts; finance does not need to pay every amount again, but only needs to check the summary table and look at the original receipts when needed. This analogy helps explain “offloading execution,” but it has an important limitation—in reality, finance might pay directly out of trust, whereas a Rollup cannot rely only on trust in the sequencer. It must rely on data availability and proof mechanisms to ensure that anyone can verify the results. This point is the focus of what comes next.
Data availability: why that “one” must let everyone audit the books
Now we come to the most easily overlooked and most critical part of Rollup security.
Imagine a situation: a batch publishes only a hash to L1—that is, a string of fingerprints computed from the batch of transaction data—but the original transaction contents are not published at all. What happens?
Outsiders can see only a fingerprint, but not the original text of any transaction. This means no one can reconstruct the state before and after execution of this batch of transactions, and therefore no one can verify whether the result submitted by the sequencer is correct. The sequencer could secretly change the state incorrectly off-chain, then publish only the corresponding summary to L1, and external observers would have no way to detect it.
This is why data availability is so important. It requires transaction data, or at least information sufficient to recover the entire state, to actually be published to L1, so that anyone can download it, reconstruct the state, and independently compute. What data availability solves is not “whether the result is correct,” but “whether you are entitled to verify the result.”
Once data is available, everything that follows can hold:
- anyone can obtain this batch of transactions, replay it themselves, and see whether the new state root is correct;
- if an error is found, a dispute or proof can be initiated;
- even if the sequencer wants to cheat, it will be exposed by the public data.
Conversely, without data availability, then whether fraud proofs or validity proofs, they can be hollowed out—if you cannot even get the original data, how can you prove that it is wrong? This is why a system that publishes only summaries and not data, even with an elaborate proof mechanism, will have greatly reduced security.
A technical comparison can illustrate this: if only a hash is published, outsiders cannot see any original transaction text; if the original transaction data is published to L1 as data (for example, in the form of calldata or blobs), then anyone can download this data and reconstruct the state. Different Rollups may currently choose different data publication methods, but the common bottom line is—there must be enough data externally to verify, rather than only hearing the operator’s one-sided account.
Data availability cost is also one of the L1 costs that a Rollup must bear. This part of the cost determines the throughput ceiling, and this point will be mentioned again in the final section.
Two paths: Optimistic Rollup and ZK Rollup
Now the question becomes: the data has been published, and L1 does not want to re-execute all transactions, so how exactly does it determine whether this batch of results is correct? Currently there are mainly two technical paths.
Optimistic Rollup: correct by default, challenged after the fact
The idea of Optimistic Rollup is straightforward: by default, every batch of transactions is correct, and the result is published first without immediate checking. To give everyone a chance to discover errors, it sets a challenge period.
During the challenge period, anyone who finds an error can submit a fraud proof, pointing out that the execution result of a certain batch of transactions is inconsistent with the actual data. If the proof succeeds, the incorrect transaction will be rolled back, and the relevant validators may suffer economic penalties. If no one raises an objection during the challenge period, the transaction will be finally confirmed.
This brings an important feature: before the challenge period ends, the transaction is not truly irreversible. The length of the challenge period is not uniformly fixed across the whole network, but is defined by each protocol itself, usually measured in days. So when you see a transaction “succeed” on an Optimistic Rollup, you should understand that it may still be some time away from final settlement.
ZK Rollup: carrying its own verifiable receipt
ZK Rollup takes another path. It does not rely on “whether someone reports it after the fact”; instead, when submitting a batch, it attaches a validity proof. This proof cryptographically shows: this batch of transactions indeed started from the correct old state and executed to produce the correct new state.
After the L1 contract receives the proof, as long as it verifies that this proof is valid, it can accept this batch of transactions. Because the proof is established at the moment it is verified, ZK Rollup does not need a long challenge period and can achieve finality faster.
The difference between these two approaches can be understood this way: Optimistic Rollup is more like a post-audit, allowing a period of time for problems to surface; ZK Rollup is more like each batch of transactions carrying a cryptographic receipt that can be verified immediately. Note that this analogy only helps distinguish the two verification methods and cannot replace understanding of data availability and the proof mechanism itself—regardless of which scheme, data availability cannot be omitted.
The trade-offs of the two paths are also clear: the Optimistic approach relies on challenge periods and economic incentives, has a relatively simple structure, but finality is slower; the ZK approach has faster finality, but places higher demands on the proof system, and generating proofs itself is more complex. But the goal of both is the same: to let L1 confirm whether the result is correct without re-executing all transactions.
The complete path from a user transaction to L1 settlement
By connecting the mechanisms above, we can see the complete process from a user clicking send to the transaction finally being finalized on Ethereum.
- The user signs and submits a transaction on L2. This transaction is not sent to the Ethereum mainnet, but to this Rollup chain, with the wallet completing the signature.
- The sequencer receives and orders the transaction. It decides in what order these transactions are processed, then packs them into a batch.
- The sequencer executes the transactions and updates the local state. After execution is complete, it obtains the new state root and the data corresponding to this batch of transactions.
- The batch data is submitted to the Rollup contract on L1. At this point L1 records this batch of data (satisfying data availability) and updates the commitment to the result summary.
- Depending on the scheme, the settlement stage begins. Optimistic Rollup waits for the challenge period to end; ZK Rollup submits a validity proof and waits for the L1 contract to verify it.
- Final confirmation at the L1 level is completed. Only at this point does the transaction truly gain the security provided by Ethereum.
This path explains why “executing on L2” and “final confirmation on L1” are two different things. The instant feedback you see on a Rollup comes from the sequencer’s execution; what truly makes it irreversible is that it completes settlement on L1. The time difference between the two is especially obvious on Optimistic Rollups.
Rollup’s boundaries and common misunderstandings
Rollups do greatly improve usable throughput and reduce costs, but they are not magic. Understanding their boundaries is necessary to set correct expectations.
First, Rollups cannot scale infinitely. They still must publish data to L1 and bear L1’s data availability cost and verification cost. This bandwidth and these fees form the throughput ceiling. No matter how efficient the proof mechanism is, as long as data still has to be published to L1, it will be constrained by L1’s data capacity.
Second, Rollup is not equal to all Layer 2. Layer 2 is an umbrella term for a major category of scaling solutions. Rollup is one path among them whose security is closer to L1, and its key feature is precisely “publishing data to L1.” Other schemes such as state channels and sidechains have different security models, and some do not rely on publishing data to L1. Treating “all L2s as Rollups” will lead people to misjudge their trust assumptions.
Third, execution on a Rollup is not the same as immediate final confirmation. Especially for Optimistic Rollups, transactions during the challenge period can still be rolled back. Treating L2 “success” as irreversible in the same way as L1 is a common misunderstanding.
Fourth, Rollup security is rooted in L1, but is also affected by L1. If L1’s data publication has problems, or the Rollup contract implementation itself has flaws, security will likewise be affected. Rollups anchor security to Ethereum, but that does not mean they automatically acquire all of Ethereum’s properties.
Fifth, Rollup does not hide data. On the contrary, its security depends on data being publicly available. A system that completely hides transaction data and publishes only summaries does not, strictly speaking, have the security guarantees required by a Rollup.
Back to the original question: how are 10,000 transactions compressed into one by a Rollup?
The answer is not that it compresses data like a zip file, but that it moves transaction execution off-chain, publishes transaction data and result commitments to L1, and turns L1 from a per-transaction executor into a settler and verifier. L1 no longer needs to repeat 10,000 executions, but it still retains the ability to verify the results through data availability and proof mechanisms.
Rollup security does not come from trusting a sequencer; it comes from allowing everyone to access the data and check the results. And precisely because it must publish this data to L1, its scaling capacity always has an upper limit—this is not a flaw, but the clear price it pays when trading security for efficiency.